Until now, keeping your website out of AI training meant a separate rule for each company's crawler. On 30 October, four of the largest AI companies said they will honor one shared rule instead. Support starts in 2027, and the details differ by company.
What Happened
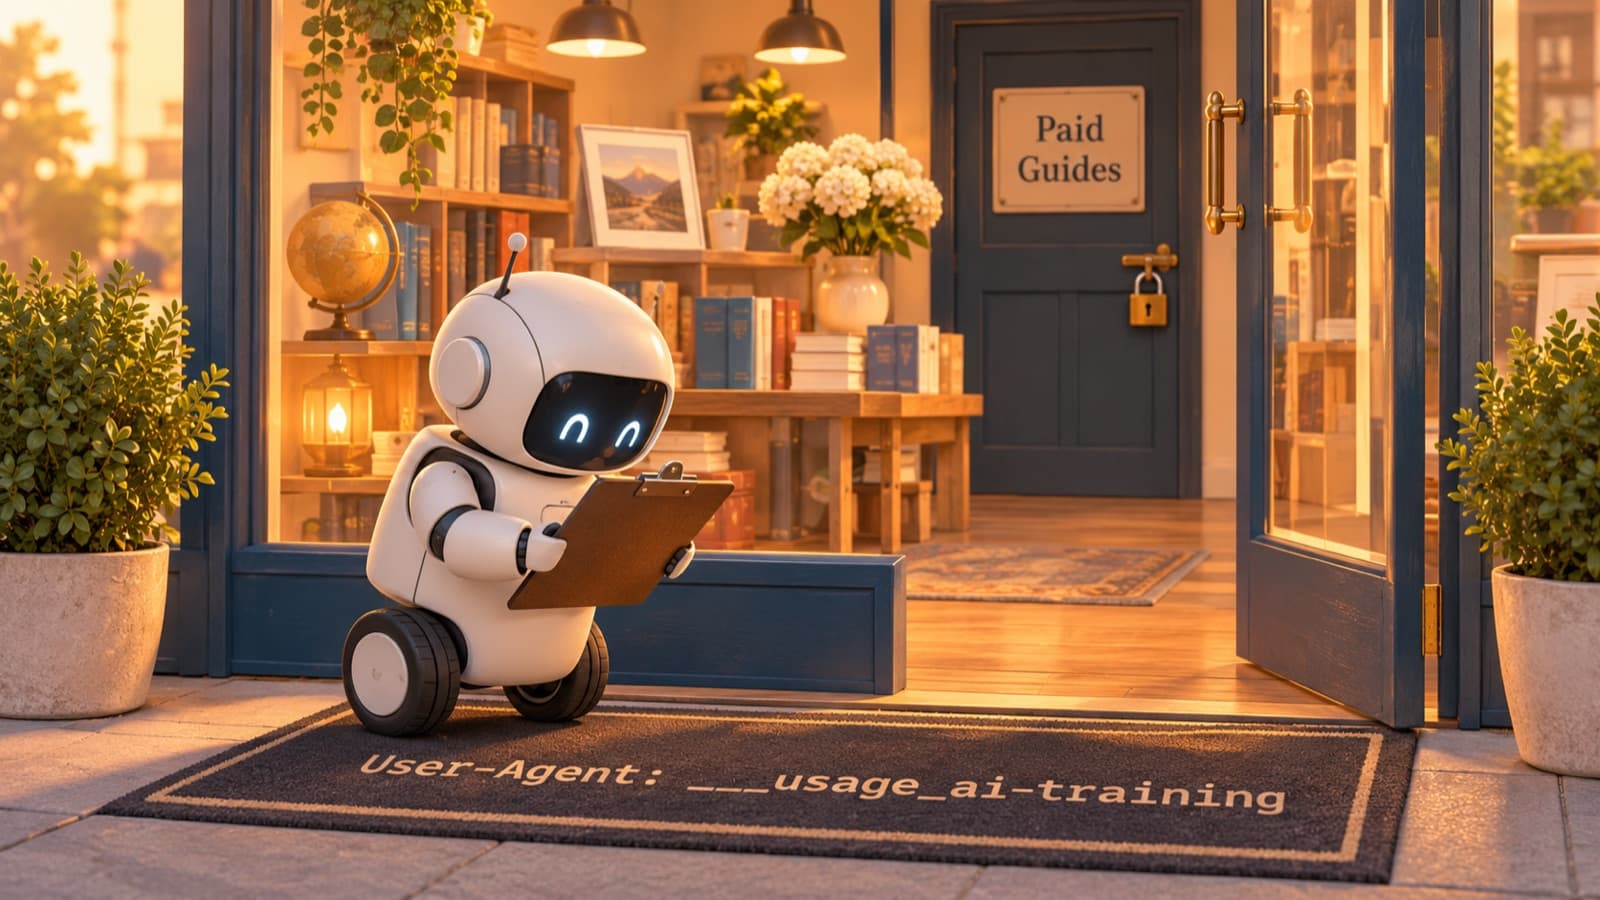
Anthropic wrote the proposal. It is an IETF Internet-Draft (opens in a new tab) that defines one robots.txt token, __usage_ai-training. The draft says it "has no formal standing in the IETF standards process." The companies adopt it voluntarily.
To opt out, a site adds a group like this to its robots.txt file:
User-Agent: __usage_ai-training
Disallow: /
Allow: /press-kit/
This example blocks AI training on every page except the press kit. The draft says a general User-Agent: * rule does not count as a training preference. You have to name the token.
Each company gives a different start date:
- Microsoft: from 1 February 2027, according to its Bing announcement (opens in a new tab).
- Google: "in early 2027," according to its crawler documentation (opens in a new tab). Google announced its support (opens in a new tab) the same day.
- OpenAI: "in the coming months," PPC Land reported (opens in a new tab). OpenAI's own post did not load for us.
- Anthropic: it "has already started implementing support," the draft's author wrote, as reported by PPC Land. Anthropic gave no date for full support.
Meta supports the idea but has not committed, SiliconANGLE reported (opens in a new tab).
What It Means for Your Business
Training and AI answers are separate choices. Training means a model learns from your pages. Grounding means an assistant reads your page to answer a question, often with a link back. Most businesses want to appear in those answers, because people now ask assistants to recommend suppliers and services.
Microsoft keeps the two apart. You can block training and still appear in Copilot answers. If you block grounding too, Microsoft warns "you will see reduced brand visibility in AI experiences." Its older NoArchive and NoCache tags stop counting as AI preferences after 1 March 2027.
Google ties them together. Google treats the shared opt-out as a block on Google-Extended, unless your file names Google-Extended itself. That token covers both Gemini training and grounding in Gemini Apps. So with Google, blocking training also removes you from Gemini app answers. Google Search stays separate. Google says Google-Extended "does not impact a site's inclusion in Google Search."
It only works going forward. The draft applies whatever preference was in place when a page was collected. Content already gathered stays in existing training sets. The signal is voluntary, with no enforcement behind it.
What to Do Next
- Decide page by page. Keep marketing and service pages open, so assistants can find and recommend you. Consider blocking paid guides, research and course material.
- Check your robots.txt file. Open it at your-domain.com/robots.txt and list the AI rules it already has. Remember that a wildcard rule says nothing about training.
- Replace old Bing tags. If you use
NoArchiveorNoCacheto limit Microsoft's AI, switch before 1 March 2027. - Test every change. One misplaced
Disallowline can hide far more of your site than you intended.
Our web and mobile team can review your site's settings and help you decide which pages to protect.